Blog

  • Integrating Generative AI in ITSM Workflows

    Integrating Generative AI in ITSM Workflows

    IT Service Management (ITSM) teams are increasingly turning to generative AI (GenAI) to streamline workflows, reduce resolution times, and improve user satisfaction. In this post, we’ll explore two architectures for integrating GenAI into platforms like ServiceNow: man-in-the-middle (human-in-the-loop) and agentic automation (autonomous AI agents).


    Why GenAI for ITSM?

    • Ticket overload: Teams handle hundreds of tickets daily, leading to burnout and delays.
    • Knowledge gaps: Agents struggle to find relevant solutions quickly.
    • Repetitive tasks: Manual triage and updates consume valuable time.

    GenAI can automate classification, suggest solutions, and even resolve incidents-but how you integrate it matters. Let’s compare two approaches.


    Architecture 1: Man-in-the-Middle (Human-in-the-Loop)

    In this approach, GenAI acts as an assistant to human agents. It analyzes tickets, suggests actions, and automates tasks but requires human approval before execution.

    Workflow Diagram:

    Use Cases:

    • High-risk scenarios (e.g., critical infrastructure changes).
    • Compliance-heavy environments (e.g., healthcare, finance).

    Implementation Steps:

    1. Set Up ServiceNow Outbound REST Integration (javascript)

    // ServiceNow Scripted REST API (Outbound)
    var request = new sn_ws.RESTMessageV2();
    request.setEndpoint('https://your-middleware.com/process-ticket');
    request.setHttpMethod('POST');
    request.setRequestBody(JSON.stringify(current));
    var response = request.execute();

    2. Build Middleware (Python/Flask Example)

    from flask import Flask, request, jsonify
    import openai

    app = Flask(__name__)
    openai.api_key = "your-api-key"

    @app.route('/process-ticket', methods=['POST'])
    def handle_ticket():
    ticket_data = request.json

    # GenAI analysis
    prompt = f"""
    Classify this ITSM ticket and suggest priority (Critical/High/Medium/Low):
    Title: {ticket_data['short_description']}
    Description: {ticket_data['description']}
    """

    response = openai.ChatCompletion.create(
    model="gpt-4",
    messages=[{"role": "user", "content": prompt}]
    )

    suggestion = response.choices[0].message['content']
    return jsonify({"suggestion": suggestion, "ticket_id": ticket_data['number']})

    3. Human Review & Action
    Agents review GenAI’s suggestions in a dashboard and approve/reject them.


    Architecture 2: GenAI Agentic Automation

    Here, GenAI agents act autonomously within guardrails. They analyze tickets, execute actions (e.g., resolving incidents, updating KBs), and only escalate exceptions to humans.

    Workflow Diagram:

    Use Cases:

    • Low-risk, repetitive tasks (e.g., password resets, FAQ responses).
    • High-volume environments needing 24/7 support.

    Implementation Steps:

    1. Autonomous Ticket Resolution with Python

    import requests
    import openai

    def resolve_ticket_automatically(ticket_id):
    # Fetch ticket from ServiceNow
    snow_url = f"https://instance.service-now.com/api/now/table/incident/{ticket_id}"
    headers = {"Accept": "application/json"}
    auth = ("admin", "password")
    response = requests.get(snow_url, headers=headers, auth=auth)
    ticket = response.json()['result']

    # GenAI analysis
    prompt = f"""
    Resolve this ticket autonomously if possible. Provide a solution and mark as closed.
    Ticket: {ticket['description']}
    """

    ai_response = openai.ChatCompletion.create(
    model="gpt-4",
    messages=[{"role": "user", "content": prompt}]
    )

    # Auto-resolve if confidence is high
    if "reset password" in ai_response.choices[0].message['content'].lower():
    update_data = {
    "state": "6", # Resolved
    "close_notes": "Automatically resolved: Password reset instructions sent."
    }
    requests.patch(snow_url, json=update_data, headers=headers, auth=auth)

    2. Guardrails for Safety

    • Limit permissions (e.g., agents can’t modify user roles).
    • Log all actions for auditing.
    • Escalate tickets containing keywords like “outage” or “data breach” to humans.

    Key Considerations

    Combined Architecture Diagram:


    Best Practices for Both Architectures

    • Data Privacy: Mask PII/PHI in tickets before sending to GenAI APIs.
    • Feedback Loops: Let agents rate AI suggestions to improve models.
    • Tooling: Use frameworks like LangChain for complex workflows.

    Conclusion

    Whether you choose man-in-the-middle or agentic automation depends on your risk tolerance and use case. Start with a hybrid approach: use autonomous agents for simple tasks (e.g., FAQs) and human-in-the-loop for critical workflows. As trust in the system grows, expand automation cautiously.

    GenAI is set to redefine ITSM, propelling organizations from automation to true intelligence. The journey is just beginning-those who embrace this shift will not only optimize IT operations but also unlock new levels of agility, resilience, and innovation. The future of ITSM is not just faster or cheaper-it’s smarter, more adaptive, and profoundly more human.

  • The Evolution of IT Infrastructure: Why Disaggregated Platforms Are the Future for GenAI

    The Evolution of IT Infrastructure: Why Disaggregated Platforms Are the Future for GenAI

    Over the past two decades, enterprise IT architecture has undergone a dramatic transformation. What began as siloed, three-tier environments has evolved through converged and hyper-converged infrastructure (HCI) to today’s cutting-edge disaggregated platforms. This journey is more than a story of hardware innovation-it’s the foundation for the next era of data-driven business, especially as generative AI (GenAI) workloads reshape the technology landscape.

    From Three-Tier to Hyper-Converged: The Drive for Simplicity

    Three-tier architecture-with separate compute, storage, and networking-offered flexibility, but at the cost of complexity and inefficiency. IT teams often faced overprovisioning, stranded resources, and operational headaches.

    The arrival of converged infrastructure bundled these elements into pre-validated stacks, simplifying procurement and deployment. Yet, the fundamental silos remained, limiting agility and resource utilization.

    Hyper-converged infrastructure (HCI) took consolidation further by merging compute and storage into modular nodes managed by software. According to Fortune Business Insights, the global HCI market is projected to reach $65 billion by 2029, reflecting enterprises’ desire for simplified management and scalability. However, HCI’s tightly coupled design makes it difficult to scale compute and storage independently-a critical limitation for today’s AI and data-intensive workloads.

    The Rise of Disaggregated Platforms: Built for GenAI

    Enter disaggregated infrastructure: an architecture that decouples compute, storage, and networking into independent resource pools. This approach is rapidly gaining traction, with the composable/disaggregated infrastructure market expected to triple to over $19 billion by 2029 (MarketsandMarkets).

    Why Disaggregation Matters-Especially for GenAI

    1. Independent Scaling GenAI workloads are unpredictable and data-hungry. Disaggregated platforms allow organizations to scale storage for massive datasets or add GPU-rich compute nodes as needed-without unnecessary overprovisioning.
    2. Superior Resource Utilization Dell reports that disaggregated architectures can deliver “orders of magnitude higher” core utilization and reduce server and software licensing costs by up to 50%.
    3. Performance for AI Technologies like NVMe-over-Fabrics and CXL memory pooling enable low-latency, high-throughput access to data-keeping GPUs saturated and AI pipelines moving at full speed.
    4. Hybrid and Edge Flexibility Disaggregated storage and compute pools can be orchestrated across on-premises, cloud, and edge environments, supporting the distributed nature of modern AI applications.

    Real-World Impact

    Industry leaders are moving fast:

    • Dell’s PowerEdge servers offer modular, independently scalable resources.
    • Many vendors/startups are rapidly evolving their portfolio to embrace disaggregation, making it the new default for enterprises scaling GenAI and other advanced workloads.
    • Edge AI is now viable, with lightweight models running inference on disaggregated clusters far from the data center.

    As Travis Vigil Vigil, SVP at Dell, puts it: “Disaggregation isn’t just about hardware-it’s about rethinking the entire data center ecosystem to unlock performance and control.”

    Looking Ahead

    The shift to disaggregated infrastructure is not just a technological trend-it’s a strategic imperative for organizations embracing GenAI and next-generation workloads. By enabling independent scaling, maximizing resource efficiency, and supporting hybrid deployment models, disaggregated platforms are redefining what’s possible in the data center.

    In the age of AI, flexibility is the ultimate competitive advantage. Is your infrastructure ready?

    Let’s connect and discuss how your organization can leverage disaggregated architectures to accelerate GenAI and future-proof your digital transformation.

  • Keep a container alive to troubleshoot it

    Containers are a great way to package code and dependencies in a portable package. This is fantastic in a world where dependencies keep getting bigger and more complex. But we are not here to discuss their benefits. If Google brought you here, more than likely you know already what a container is and you are trying to troubleshoot one. If that’s the case, I hope you find useful the tip I am about to tell you.

    To understand the solution we must first remember that containers are designed to run a task as soon as they start. You define such task with either CMD or ENTRYPOINT. The problem is that if the task dies the container dies too and you can’t log in into it to find out what happened. Sometimes “docker logs” will give you a hint of what’s happening but other times you wish you could simply log in to the container and check things out, but of course you can’t because the container is dead

    A solution I have become fond of is to override the ENTRYPOINT with a process that keeps the container alive and then open a terminal session into it. Let me give you an example.

    IMPORTANT: I am using Podman but all of this will work perfectly fine with Docker as well. This is the “Dockerfile“. Notice how the main task for this container is “python app.py“

    FROM python:3.10.5
    WORKDIR /app
    COPY . /app
    RUN pip install --no-cache-dir -r requirements.txt
    EXPOSE 7860
    CMD ["python", "app.py"]

    This is the code contained in “app.py“. It is a simple Gradio chatbot. It gets the users prompt and sends an API call to to get a response.

    import gradio as gr
    import os, requests, import urllib3
    urllib3.disable_warnings()
    
    appurl = os.environ["APP_URL"]
    
    def give_response(query, history):
        payload = {"query": query}
        response = requests.post(appurl, json=payload)
        return response.json()["response"]
    
    demo = gr.ChatInterface(
                  give_response,
                  type = "messages",
                  title="My first Chatbot",
                  description="Ask me a question, don't be shy")
    
    demo.launch(server_name="0.0.0.0")

    As you can see the code requires us to define an environment variable “APP_URL” with the URL to send the request to. Let’s say that we don’t define the variable and attempt to run the container.

    pi@piper1:~$ podman run -d -p 7860:7860 localhost/blog:v1
    19dc02db0b2e06c51756c7f55a3eb861c11f831a21574efdcd2e00081c9191a1
    pi@piper1:~$ podman ps -a
    CONTAINER ID  IMAGE              COMMAND        CREATED        STATUS      NAMES
    19dc02db0b2e  localhost/blog:v1  python app.py  3 seconds ago  Exited (1)  dry_rice

    As expected the container fails but here is the trick … we run it again but we use the “–entrypoint” argument to run “tail -f /dev/null“. The container is not changing we are simply overriding “python app.py” with this “tail” command which stays running and in doing so keeps the container alive. Notice the “single quote” around the square brackets.

    pi@piper1:~$ podman run -d --entrypoint='["tail", "-f", "/dev/null"]' -p 7860:7860 localhost/blog:v1
    e1031d4c2ecbf3d4ec244aef262e71fb2f4e227154b6e22eabf634e4e053f4a0
    pi@piper1:~$ podman ps
    CONTAINER ID  IMAGE              STATUS        PORTS                   NAMES
    e1031d4c2ecb  localhost/blog:v1  Up 6 seconds  0.0.0.0:7860->7860/tcp  sour_soup

    Now we can login into the container and do whatever checks we need to do. We can even run “python app.py” and see what’s going on live.

    pi@piper1:~$ podman exec -it e1031d4c2ecb /bin/bash
    root@e1031d4c2ecb:/app# ls -l
    total 12
    -rw-r--r-- 1 root root 518 Mar 24 04:35 Dockerfile
    -rw-r--r-- 1 root root 566 Mar 24 04:35 app.py
    -rw-r--r-- 1 root root 897 Mar 24 04:35 requirements.txt
    root@e1031d4c2ecb:/app# python3 app.py
    Traceback (most recent call last):
      File "/app/app.py", line 7, in <module>
        appurl = os.environ["APP_URL"]
      File "/usr/local/lib/python3.10/os.py", line 679, in __getitem__
        raise KeyError(key) from None
    KeyError: 'APP_URL'

    This was a simplistic example but you get point. There could be a file or a path missing, a typo, a permissions issue … by using this trick you can troubleshoot interactively inside the container. Once you know what the issue is you can fix your files and rebuild the container image.

    The next question is, can you do this in Kubernetes as well? Yes, you can add the “command” to the “Deployment”, not to the “Pod”. This is a list of strings as you see in the last line in the simplified manifest below.

    apiVersion: v1
    kind: Deployment
    metadata:
      name: blog
    spec:
      containers:
      - name: blog-container
        image: debian
        command: ["tail", "-f", "/dev/null"]

    As soon as I save the changes to the deployment manifest, Openshift creates a new pod and kills the old one. Then I can terminal into the new pod and browse around. Notice I can even launch the application from the terminal session.

    $ pwd         
    /app
    $ ls -l
    total 12
    -rw-r--r--. 1 root root 518 Mar 24 04:35 Dockerfile
    -rw-r--r--. 1 root root 566 Mar 24 04:35 app.py
    -rw-r--r--. 1 root root 897 Mar 24 04:35 requirements.txt
    $ ps -ef
    UID          PID    PPID  C STIME TTY          TIME CMD
    1000770+       1       0  0 00:00 ?        00:00:00 tail -f /dev/null
    1000770+       7       0  0 00:00 pts/0    00:00:00 sh -i -c TERM=xterm sh
    1000770+      13       7  0 00:00 pts/0    00:00:00 sh
    1000770+      90      13  0 00:02 pts/0    00:00:00 ps -ef
    
    $ python3 app.py
    * Running on local URL:  http://0.0.0.0:7860
    
    To create a public link, set `share=True` in `launch()`.

    Of course, this is only intended for troubleshooting. Once you find out what’s wrong you can fix the image and manifest and deploy them again.

  • GenAI as a Replacement for Enterprise Search: Revolution or Evolution?

    GenAI as a Replacement for Enterprise Search: Revolution or Evolution?

    Enterprise search has long been the backbone of organizational knowledge discovery, enabling employees to sift through vast troves of internal data-emails, documents, reports, and more. Yet, as information volume and complexity have exploded, traditional search systems have struggled to keep pace. Enter Generative AI (GenAI): a transformative technology that promises not just incremental improvements, but a fundamental reimagining of how enterprises access and leverage information.

    The Traditional Enterprise Search Challenge

    Legacy enterprise search platforms typically rely on keyword-matching and index-based algorithms. While effective for straightforward queries, these systems falter when faced with:

    • Ambiguous or complex natural language queries
    • Unstructured or poorly tagged data
    • Industry-specific jargon and synonyms
    • The need for contextual, role-based, or personalized results
    • Multi-language demands and adaptive access controls

    The result? Knowledge workers spend an estimated 2.5 to 3.6 hours per day searching for information, leading to frustration and lost productivity.

    How GenAI Transforms Enterprise Search

    GenAI, powered by large language models (LLMs) and advanced natural language processing (NLP), addresses these pain points in several critical ways:

    1. Deep Contextual Understanding and Intent Detection

    Unlike traditional search, GenAI interprets the context and underlying intent behind user queries. Whether an employee asks, “How do I reset my password?” or “I forgot my password, can you help?”-GenAI recognizes the shared intent and delivers precise, relevant answers. This semantic understanding extends to complex, multi-step, or follow-up queries, enabling conversational and intuitive information retrieval.

    2. Personalization and Adaptive Learning

    GenAI-powered search systems learn from user profiles, search histories, and real-time interactions, tailoring results to individual roles and preferences. Over time, this leads to hyper-personalized experiences, with the system anticipating user needs and improving with every interaction.

    3. Mastery of Unstructured and Multilingual Data

    GenAI excels at parsing unstructured data-emails, PDFs, images-transforming them into structured, searchable formats. It also supports multilingual and cross-domain queries, making it invaluable for global enterprises with diverse data sources.

    4. Automation and Decision Support

    Beyond search, GenAI can automate clerical tasks-summarizing documents, drafting emails, compiling reports-freeing employees to focus on higher-value work. It can synthesize insights across multiple sources, supporting faster and more informed decision-making.

    5. Enhanced Security and Compliance

    Modern GenAI enterprise search solutions integrate robust access controls and compliance features, ensuring sensitive information is only accessible to authorized users. AI can also detect anomalies and potential security threats by analyzing usage patterns.

    Real-World Impact

    Leading organizations are already leveraging GenAI to revolutionize internal knowledge centers, streamline customer service, and optimize business processes. The result is a measurable boost in productivity, faster decision cycles, and significant cost savings.

    Challenges and Considerations

    Despite its promise, GenAI is not a panacea. Key challenges include:

    • Data Quality and Integration: Success depends on clean, well-organized data and seamless integration with existing systems.
    • Hallucination Risk: LLMs may generate plausible but incorrect answers if not properly constrained by retrieval-augmented generation (RAG) or domain-specific fine-tuning.
    • Security and Governance: Ensuring robust access controls and preventing prompt-based security bypasses remain ongoing concerns.
    • Infrastructure Readiness: Many enterprises lack the foundational data infrastructure and skilled workforce needed for successful GenAI deployment.

    Is GenAI a Replacement or an Evolution?

    While GenAI dramatically elevates enterprise search, it is best viewed not as a wholesale replacement, but as an evolutionary leap. GenAI augments and, in many cases, supersedes traditional search by delivering context-aware, conversational, and highly relevant results. However, its success hinges on thoughtful implementation, robust data governance, and continuous improvement.

    “GenAI is no magic bullet, but applied in the right places it has potential to improve enterprise search… As the technology evolves, its ability to further enhance search capabilities will grow, offering even more refined solutions to complex search challenges.”

    The Future: From Search to Knowledge Discovery

    As GenAI matures, the line between search and intelligent knowledge discovery will blur. Enterprises that invest in GenAI-powered search today are not just making information easier to find-they are laying the groundwork for a future where knowledge is proactively surfaced, synthesized, and delivered in context, driving innovation and competitive advantage.

    In summary: GenAI is not just a better search engine-it is the catalyst for a new era of enterprise intelligence. For organizations ready to embrace this shift, the rewards are substantial: more empowered employees, faster insights, and a culture of data-driven excellence.

  • Podman build fails with /etc/passwd: permission denied

    A short post today to share an issue that troubled me for a while. Hopefully it can help you too.

    Basically I was trying to build a new container image using Podman in Ubuntu. These are my versions:

    • Ubuntu 24.04.2 LTS
    • podman version 4.9.3

    My Dockerfile is straight forward

    FROM python:3.10.5
    WORKDIR /app
    COPY . /app
    RUN pip install --no-cache-dir -r requirements.txt
    CMD ["python", "app.py"]

    When I tried to create the container image I get the following output

    (env) user1@mytpl:~/Desktop/myapp$ podman build -t myapp:v1 .
    STEP 1/6: FROM python:3.10.5
    Resolved "python" as an alias (/etc/containers/registries.conf.d/shortnames.conf)
    Trying to pull docker.io/library/python:3.10.5...
    Getting image source signatures
    Copying blob 588423e31bcf done   |
    Copying blob 001c52e26ad5 done   |
    Copying blob 2068746827ec done   |
    Copying blob d9d4b9b6e964 done   |
    Copying blob 8a335986117b done   |
    Copying blob 9daef329d350 done   |
    Copying blob ecb6a3f01c0d done   |
    Copying blob 00d40f20f0cf done   |
    Copying blob 5d588b4f3b55 done   |
    Error: creating build container: copying system image from manifest list: writing blob: adding layer with blob "sha256:001c52e26ad57e3b25b439ee0052f66           92e5c0f2d5d982a00a8819ace5e521452": processing tar file(open /etc/passwd: permission denied): exit status 1

    In the end I tracked it down to a service called “mfetpd.service” which appears to be some Trellix endpoint security software.

    (env) user1@mytpl:~/Desktop/myapp$ sudo systemctl status mfetpd.service
    ● mfetpd.service - Trellix Endpoint Security for Linux Threat Prevention
         Loaded: loaded (/usr/lib/systemd/system/mfetpd.service; enabled; preset: enabled)
         Active: active (running) since Mon 2025-03-24 14:35:44 +08; 5min ago
           Docs: man:mfetpd(8)
        Process: 30546 ExecStartPre=/opt/McAfee/ens/tp/scripts/aac-control-wrapper.sh systemd (code=exited, status=0/SUCCESS

    The solution was to temporarily stop this service to build the container image

    sudo systemctl stop mfetpd.service
    podman build ...
    sudo systemctl start mfetpd.service

    Once the image “python:3.10.5” layer is downloaded I am able to build more containers using the same version of Python without having to pause the “mfetpd” service which makes my security team happy.

    I hope this helps you same some of your precious time!

  • Infrastructure as Code (IaC) Security Best Practices

    Infrastructure as Code (IaC) Security Best Practices

    Infrastructure as Code (IaC) has revolutionized how we provision and manage infrastructure, enabling speed, repeatability, and scalability. However, as with any code, IaC introduces new security considerations. Misconfigurations, exposed secrets, and lack of visibility can lead to significant risks in production environments.

    This guide explores actionable best practices for securing your Terraform, Ansible, and other IaC pipelines-helping you build robust, compliant, and resilient infrastructure. Sample code and how-to notes included!


    1. Treat IaC Like Application Code

    Just as you would with application code, store your IaC in version control systems (e.g., Git). This enables:

    • Change tracking: Who changed what, when, and why.
    • Peer reviews: Enforce code reviews and approvals before merging.
    • Rollback: Revert to previous known-good states if issues arise.

    Tip:
    Use branch protection rules and require pull request reviews for all changes.


    2. Secrets Management

    Never hard-code secrets or sensitive data (API keys, passwords, certificates) in your IaC files. Instead:

    • Use secret management tools like HashiCorp Vault, AWS Secrets Manager, or Azure Key Vault.
    • Integrate secrets into your pipelines at runtime, not in code.
    • Leverage environment variables or encrypted files for sensitive values.

    Sample: Fetching Secrets from Vault in Terraform

    provider "vault" {
      address = "https://vault.example.com"
    }
    
    resource "vault_generic_secret" "example" {
      path = "secret/data/myapp"
    }
    
    output "db_password" {
      value = vault_generic_secret.example.data["password"]
    }

    How-to:

    • Replace https://vault.example.com with your Vault server address.
    • The vault_generic_secret resource fetches secrets dynamically.
    • Output blocks can reference secrets securely-never hardcode them!

    Sample: Encrypting Secrets in Ansible with ansible-vault

    - hosts: all
      vars_files:
        - secrets.yml
      tasks:
        - name: Use secret password
          debug:
            msg: "The password is {{ secret_password }}"

    How-to:

    • Create and encrypt the secrets file: ansible-vault create secrets.yml
    • Reference the encrypted file in your playbook under vars_files.
    • Access secrets in tasks using Jinja2 templating, e.g., {{ secret_password }}.

    3. Automated Security Scanning

    Integrate security tools into your CI/CD pipeline to catch misconfigurations and vulnerabilities early:

    Sample: Terraform Security Scanning with tfsec in GitHub Actions

    name: Terraform Security Scan
    
    on: [push]
    
    jobs:
      tfsec:
        runs-on: ubuntu-latest
        steps:
          - uses: actions/checkout@v2
          - name: Run tfsec
            uses: aquasecurity/tfsec-action@v1
            with:
              tfsec_version: 'latest'

    How-to:

    • Add this workflow to your .github/workflows directory.
    • The scan will fail the build if critical security issues are found, helping you catch problems early.

    4. Principle of Least Privilege

    Ensure that your IaC tools, pipelines, and the resources they provision follow the principle of least privilege:

    • Limit IAM permissions for automation accounts.
    • Avoid using overly broad roles or root accounts.
    • Regularly audit permissions and remove unnecessary access.

    5. Policy as Code

    Define and enforce security and compliance policies programmatically:

    • Use tools like Open Policy Agent (OPA), Sentinel (for Terraform Cloud), or Conftest.
    • Enforce rules such as “no public S3 buckets,” “encryption enabled,” or “no hardcoded credentials.”

    Example:
    OPA policies can block deployments that violate security standards before they reach production.


    6. Continuous Monitoring and Drift Detection

    Even after deployment, infrastructure can drift from the desired state:

    • Use tools like Terraform Cloud, AWS Config, or Driftctl to detect and remediate drift.
    • Set up alerts for unauthorized changes and automate remediation where possible.

    7. Regular Reviews and Updates

    IaC modules and dependencies evolve-so should your security practices:

    • Schedule regular reviews of your IaC codebase and third-party modules.
    • Update modules to patch vulnerabilities and leverage new security features.
    • Document your security practices and train your team.

    Conclusion

    Securing Infrastructure as Code is not a one-time task, but a continuous process woven into your development and deployment lifecycle. By treating IaC like application code, managing secrets securely, automating scanning, enforcing least privilege, and using policy as code, you can drastically reduce risk and build trust in your automation.

  • How to Benchmark Enterprise Storage: Fio and Vdbench Explained

    How to Benchmark Enterprise Storage: Fio and Vdbench Explained

    Enterprise storage arrays from vendors like Dell EMC, NetApp, and Pure Storage are the foundation of mission-critical IT environments. Ensuring these systems deliver consistent, high performance under real-world workloads is essential for application reliability and business continuity. In this post, we’ll explore how to benchmark enterprise storage using two industry-leading tools- Fio and Vdbench– with practical configuration examples and best practices.

    Why Benchmarking Enterprise Storage is Unique

    Enterprise arrays are not just fast disks-they’re complex systems with:

    • Multiple controllers and cache layers
    • Advanced data protection (RAID, erasure coding)
    • High-speed protocols (Fibre Channel, iSCSI, NVMe-oF)
    • Storage tiering and virtualization
    • Multi-protocol (block, file) support

    Benchmarking these systems is different from testing a single SSD or HDD. You must simulate production-like workloads, test at scale, and observe performance under both normal and failure conditions.

    Best Practices for Enterprise Storage Benchmarking

    • Simulate real-world workloads: Use realistic mixes of random/sequential I/O, read/write ratios, and block sizes.
    • Test at scale: Ensure test data sets exceed cache sizes and run with sufficient concurrency.
    • Run long-duration tests: Observe steady-state performance, not just short-term cache hits.
    • Monitor the full stack: Track storage, network, and server metrics.
    • Document everything: Record hardware/software versions, configurations, and test parameters.
    • Include failure scenarios: Simulate controller or network failures to test resilience.

    Fio: Flexible I/O Tester

    Fio is a versatile, scriptable tool ideal for generating a wide range of I/O workloads against enterprise storage.

    Example Fio Job File for Enterprise Storage
    text[global]
    ioengine=libaio
    direct=1
    rw=randrw
    rwmixread=70
    bs=8k
    iodepth=64
    numjobs=8
    size=100G
    runtime=3600
    time_based
    group_reporting
    filename=/dev/sdx # Replace with your LUN or device

    [verify]
    verify=crc32

    What this does:

    • Simulates a 70% read/30% write random workload with 8KB blocks.
    • Runs 8 parallel jobs with a queue depth of 64 for 1 hour.
    • Uses direct I/O to bypass the OS cache.
    • Verifies data integrity with CRC32.

    Run it with:

    sudo fio enterprise_test.fio

    Tips:

    • Use multiple devices or files to simulate multi-volume workloads.
    • Adjust concurrency (numjobs, iodepth) to match your environment.
    • Use --output-format=json for detailed reporting.

    Vdbench: Enterprise Workload Generator

    Vdbench is designed for complex, multi-host enterprise storage validation and offers granular workload definition and data validation.

    Example Vdbench Configuration
    text# Storage Definitions for multiple LUNs
    sd=sd1,lun=/dev/sdb,size=100g,openflags=o_direct
    sd=sd2,lun=/dev/sdc,size=100g,openflags=o_direct
    sd=sd3,lun=/dev/sdd,size=100g,openflags=o_direct
    sd=sd4,lun=/dev/sde,size=100g,openflags=o_direct

    # Workload Definition: 67% read, 33% write, 8KB random
    wd=wd1,sd=(sd1-sd4),xfersize=8k,rdpct=67,seekpct=100

    # Run Definition: max I/O, 24 hours, 1s reporting
    rd=rd1,wd=wd1,iorate=max,elapsed=86400,interval=1

    Run it with:

    vdbench -f enterprise_vdbench.conf

    Advanced tips:

    • Use the hd section to define multiple hosts for distributed testing.
    • Simulate failures (e.g., disconnect a path or controller) during the run to observe failover behavior.
    • Use fsd and fwd for NAS/file workloads.

    Key Steps for Success

    1. Profile your workload: Know your application’s I/O patterns. (capture the workload IO pattern)
    2. Prepare your environment: Use dedicated test LUNs/volumes.
    3. Configure your tools: Use Fio or Vdbench job files that match your workload.
    4. Run and monitor: Capture storage, host, and network metrics.
    5. Analyze results: Look for steady-state performance, latency spikes, and the impact of failures.
    6. Document and repeat: Ensure tests are reproducible and results are transparent.

    Conclusion

    Benchmarking enterprise-class storage is about more than just peak numbers-it’s about understanding how your array performs under pressure, during failures, and with your real workloads. Tools like Fio and Vdbench provide the flexibility, power, and validation features needed for accurate, actionable results. By following best practices and using realistic configurations, you can ensure your storage infrastructure is ready for the demands of the modern enterprise.

    References:

    • SNIA Storage Performance Testing Guide
    • Fio and Vdbench Official Documentation
  • Ubuntu VMs get same IP from DCHP in vSphere

    The problem

    This is a quick post to present a solution to this problem that bugged me for a while. If you are using Ubuntu as the guest OS for vSphere virtual machines you might encounter this problem. I was running Ubuntu 22.04 but I think it might be the same problem for other versions.

    Every new VM I created was getting the same IP address from the DCHP server even though the MAC address was different.

    The explanation

    I had a Ubuntu VM template configured for DHCP as follows:

    root@albmtest:~# cat /etc/netplan/99-netcfg-vmware.yaml
    # Generated by VMWare customization engine.
    network:
      version: 2
      renderer: networkd
      ethernets:
        ens160:
          dhcp4: yes
          dhcp4-overrides:
            use-dns: false
          nameservers:
            addresses:
              - 172.24.1.10

    The explanation is that by default Ubuntu’s Netplan doesn’t use the MAC address for DHCP. By default it uses the “machine-id”. This is explained in this paragraph of the Netplan documentation.

    So, unless you set “dhcp-identifier” to “mac“, by default netplan uses “machine-id“. You can find this in “/etc/machine-id” inside the VM. But as I found out, it transpires VMware doesn’t change regenerate “/etc/machine-id” in the guest by default. When you put those 2 default behaviors together you get a problem.

    The Solution

    You can solve this by either:

    • erasing the machine-id before creating a template by running “echo > /etc/machine-id“
    • editing the netplan yaml file to force it to use “mac” addresses for DHCP
    root@albmtest:~# cat /etc/netplan/99-netcfg-vmware.yaml
    # Generated by VMWare customization engine.
    network:
      version: 2
      renderer: networkd
      ethernets:
        ens160:
          dhcp4: yes
          dhcp4-overrides:
            use-dns: false
          dhcp-identifier: mac
          nameservers:
            addresses:
              - 172.24.1.10

    If you modify “netplan” don’t forget to “apply” to make sure any changes you make are activated.

    root@albmtest:~# netplan apply

    Final TIP: when you are testing your changes, you can force the DHCP client to renew the IP like this

    root@albmtest:~# dhclient -r

    I hope this post saved you some trouble. Good luck!

  • Using Ansible to run Terraform plans

    Yes, your eyes are not deceiving you 🙂 Usually, when the words Ansible and Terraform appear in the same sentence is for the opposite scenario. Many articles out there provide examples of using Terraform to deploy infrastructure followed by running Ansible to configure it using the local-exec provisioner. This is a good thing because, if you need some post-provisioning configuration, it is better to rely on another declarative and idempotent tool like Ansible, rather than invoking shell scripts.

    But in this post we are not going to do any of that. What we are going to do is the other way around. We are going to have an Ansible playbook that runs your Terraform plan.

    This article is a follow up from a series of posts to introduce infrastructure admins and engineers to Terraform and to explain how to use it to manage on-prem physical infrastructure in a datacenter. You can find access the full series here.

    Reasons to do it

    But why? Well, if you have an physical infrastructure background and are running a traditional datacenter more than likely you have been playing with Ansible. Chances are you started with Ansible running in the command line and hard-coding your infrastructure’s credentials inside the playbook. Then you evolved into using an external credentials file and encrypting it using “ansible-vault”. Eventually you might have deployed Ansible AWX or even RedHat AAP. At this point, you are enjoying RBAC (who can run what playbook and on what infrastructure) and amazing (there is no other way to put it) credential management.

    Then, you talk to your developers over coffee and they tell you about Terraform. But when you get familiar with it, you discover that unless you pay for a SaaS offering you are stuck in the “command-line with hard-coded credentials” scenario. Wouldn’t it be great if you could use AWX to run Terraform? You could enjoy RBAC and credential management and all the other goodness that it provides. This is possible thanks to Ansible’s Terraform module.

    First steps

    Let’s say we have a very basic Terraform project to create a storage group in Dell PowerMax. The “main.tf” shown below starts the PowerMax provider and then creates a storage group “terraform_sg”. I don’t think it is strictly necessary, but if you are interested in learning more about provisioning storage in Dell PowerMax you can check out this previous post. For simplicity we haven’t created or referenced any variables. All the information is contained into a single file, the “main.tf” shown below.

    terraform {
      required_providers {
        powermax = {
          source = "dell/powermax"
        }
      }
    }
    
    provider "powermax" {
      username      = "smc"
      password      = "TFp2ssw0rd"
      endpoint      = "https://10.1.2.3:8443"
      serial_number = "000123456789"
      pmax_version  = 100
      insecure      = true
    }
    
    resource "powermax_storagegroup" "tf_sg" {
      name          = "terraform_sg"
      srp_id         = "SRP_1"
    }

    In the same machine we have both Terraform and Ansible installed. In order to run the above Terraform plan with Ansible, we need at a minimum a playbook that looks like follows. It needs to include two mandatory parameters: “project_path” and “state”. The first parameter specifies the directory that contains the plan, ie the “main.tf” and typically any other files like “variables.tf”. My Ansible playbook is called “runtf.yml”.

    ---
    - hosts: localhost
      gather_facts: no
    
      vars:
        project_dir: "/root/powermax" # folder that contains main.tf, ...
    
      tasks:
        - name: Run terraform
          community.general.terraform:
            project_path: '{{ project_dir }}'
            state: present
          register: output
    
        - debug:
            var: output

    As you can see I have registered the output of the terraform task and then created a second task to print it out on the terminal so that we can get more details. All is left now is to run it using the “ansible-playbook” command

    root@alb-terraform:~# ansible-playbook runtf.yml
    
    PLAY [localhost] ***************************************************************************************
    
    TASK [Run terraform] ***************************************************************************************
    changed: [localhost]
    
    TASK [debug] ***************************************************************************************
    ok: [localhost] => {
        "output": {
            "changed": true,
            "command": "/usr/bin/terraform apply -no-color -input=false -auto-approve -lock=true /tmp/tmpjaojemdl.tfplan",
            "failed": false,
            "outputs": {},
            "state": "present",
            "stderr": "",
            "stderr_lines": [],
            "stdout": "powermax_storagegroup.tf_sg: Creating...\npowermax_storagegroup.tf_sg: Creation complete after 0s [id=terraform_sg]\n\nApply complete! Resources: 1 added, 0 changed, 0 destroyed.\n",
            "stdout_lines": [
                "powermax_storagegroup.tf_sg: Creating...",
                "powermax_storagegroup.tf_sg: Creation complete after 0s [id=terraform_sg]",
                "",
                "Apply complete! Resources: 1 added, 0 changed, 0 destroyed."
            ],
            "workspace": "default"
        }
    }
    
    PLAY RECAP ***************************************************************************************
    localhost  : ok=2    changed=1    unreachable=0    failed=0    skipped=0    ignored=0

    Ansible run Terraform, and Terraform managed to make the changes so as expected, Ansible reports the task as “changed”. In the “debug” task, notice the “command” parameter. This is how Ansible is invoking Terraform. This invocation includes the “-auto-approve” flag so that Terraform doesn’t look for confirmation. The “stdout” and stdout_lines” parameters show the output that has been captured from Terraform about the creation of the different resources .

    A very important feature of both Ansible and Terraform is idempotency, ie the ability to run the same code repeatedly without making any damage. Let’s run it again and observe what happens.

    root@alb-terraform:~# ansible-playbook runtf.yml
    
    PLAY [localhost] ***************************************************************************************
    
    TASK [Run terraform] ***************************************************************************************
    ok: [localhost]
    
    TASK [debug] ***************************************************************************************
    ok: [localhost] => {
        "output": {
            "changed": false,
            "command": "/usr/bin/terraform apply -no-color -input=false -auto-approve -lock=true /tmp/tmp718kkwbo.tfplan",
            "failed": false,
            "outputs": {},
            "state": "present",
            "stderr": "",
            "stderr_lines": [],
            "stdout": "powermax_storagegroup.tf_sg: Refreshing state... [id=terraform_sg]\n\nNo changes. Your infrastructure matches the configuration.\n\nTerraform has compared your real infrastructure against your configuration\nand found no differences, so no changes are needed.\n",
            "stdout_lines": [
                "powermax_storagegroup.tf_sg: Refreshing state... [id=terraform_sg]",
                "",
                "No changes. Your infrastructure matches the configuration.",
                "",
                "Terraform has compared your real infrastructure against your configuration",
                "and found no differences, so no changes are needed."
            ],
            "workspace": "default"
        }
    }
    
    PLAY RECAP ***************************************************************************************
    localhost : ok=2    changed=0    unreachable=0    failed=0    skipped=0     ignored=0
    

    As expected, Ansible is reporting “ok”, which means the current state matched the desired state and therefore no changes were made. It has also captured the relevant from Terraform stating the same thing.

    Using variables

    This is a good start but ideally we would like to have the ability to make the plan more flexible by using variables for information such as the storage group name in this case. We can modify the “main.tf” as follows. Notice how the “default” value of the variable is commented out. It doesn’t matter if it is commented or not because when we invoke Terraform with external variables we overwrite the default value defined in the variable blocks.

    terraform {
      required_providers {
        powermax = {
          source = "dell/powermax"
        }
      }
    }
    
    provider "powermax" {
      username      = "smc"
      password      = var.password
      endpoint      = "https://10.1.2.3:8443"
      serial_number = "000123456789"
      pmax_version  = 100
      insecure      = true
    }
    
    variable "sg_name" {
     description = "Name of volume to create"
     type        = string
     #default     = "terraform_sg"
    }
    
    variable "password" {
      type        = string
      description = "Stores the password of Unisphere."
      #default = ""
    }
    
    resource "powermax_storagegroup" "tf_sg" {
      name          = var.sg_name
      srp_id         = "SRP_1"
    }

    Additionally, notice how in the “provider” block we have also referenced another variable for the “password”. For security reasons we might want to have, sensitive information like that, stored in a separate file and protect it. In this case we haven’t even declared a default value because we can leverage ansible-vault or AWX to encrypt it and to pass it to Terraform at run time.

    Now, the corresponding Ansible playbook needs to use the “variables” parameter. This parameter essentially converts each of the variables into a “-var” flag when invoking Terraform.

    ---
    - hosts: localhost
      gather_facts: no
    
      vars:
        project_dir: "/root/powerstore" # folder that contains main.tf, ...
    
      tasks:
        - name: Run terraform
          community.general.terraform:
            project_path: '{{ project_dir }}'
            state: present
            variables:
              sg_name: "{{ vol_name }}"
              password: "{{ password }}"
          register: output
    
        - debug:
            var: output

    Now, at runtime we are going to select a different storage group name. The storage group is created as expected and the relevant Terraform output is captured.

    root:~# ansible-playbook runtf.yml --extra-vars "sg_name=tf-sg2 password=TFp2ssw0rd"
    
    PLAY [localhost] ***************************************************************************************
    
    TASK [Run terraform] ***************************************************************************************
    changed: [localhost]
    
    TASK [debug] ***************************************************************************************
    ok: [localhost] => {
        "output": {
            "changed": true,
            "command": "/usr/bin/terraform apply -no-color -input=false -auto-approve -lock=true /tmp/tmpimdwzdu1.tfplan",
            "failed": false,
            "outputs": {},
            "state": "present",
            "stderr": "",
            "stderr_lines": [],
            "stdout": "powermax_storagegroup.tf_sg: Creating...\npowermax_storagegroup.tf_sg: Creation complete after 5s [id=vol1]\n\nApply complete! Resources: 1 added, 0 changed, 0 destroyed.\n",
            "stdout_lines": [
                "powermax_storagegroup.tf_sg: Creating...",
                "powermax_storagegroup.tf_sg: Creation complete after 5s [id=vol1]",
                "",
                "Apply complete! Resources: 1 added, 0 changed, 0 destroyed."
            ],
            "workspace": "default"
        }
    }
    
    PLAY RECAP ***************************************************************************************
    localhost  : ok=2    changed=1    unreachable=0    failed=0    skipped=0    ignored=0

    Terraform plan

    We went straight to “terraform apply” but most Terraform workflows also include running the plan command first. This is done with Ansible by running the playbook in “check mode”. Check mode invokes “terraform plan” for us.

    root:~# ansible-playbook runtf.yml --check --extra-vars "sg_name=tf-sg3 password=TFpass"
    
    PLAY [localhost] ***************************************************************************************
    
    TASK [Run terraform] ***************************************************************************************
    ok: [localhost]
    
    TASK [debug] ***************************************************************************************
    ok: [localhost] => {
        "output": {
            "changed": false,
            "command": "/usr/bin/terraform apply -no-color -input=false -auto-approve -lock=true /tmp/tmp6f2o83k5.tfplan",
            "failed": false,
            "outputs": {},
            "state": "present",
            "stderr": "",
            "stderr_lines": [],
            "stdout": "powermax_storagegroup.tf_sg: Refreshing state... [id=tf-sg2]\n\nTerraform used the selected providers to generate the following execution\nplan. Resource actions are indicated with the following symbols:\n  ~ update in-place\n\nTerraform will perform the following actions:\n\n  # powermax_storagegroup.tf_sg will be updated in-place\n  ~ resource \"powermax_storagegroup\" \"tf_sg\" {\n      ~ cap_gb                   = 0 -> (known after apply)\n      + child_storage_group      = (known after apply)\n      ~ compression              = true -> (known after apply)\n      + compression_ratio        = (known after apply)\n      ~ compression_ratio_to_one = 0 -> (known after apply)\n      + device_emulation         = (known after apply)\n      ~ id                       = \"tf-sg2\" -> (known after apply)\n      + maskingview              = (known after apply)\n      ~ name                     = \"tf-sg2\" -> \"tf-sg3\"\n      ~ num_of_child_sgs         = 0 -> (known after apply)\n      ~ num_of_masking_views     = 0 -> (known after apply)\n      ~ num_of_parent_sgs        = 0 -> (known after apply)\n      + num_of_snapshot_policies = (known after apply)\n      ~ num_of_snapshots         = 0 -> (known after apply)\n      ~ num_of_vols              = 0 -> (known after apply)\n      + parent_storage_group     = (known after apply)\n      + service_level            = (known after apply)\n      ~ slo                      = \"NONE\" -> (known after apply)\n      ~ slo_compliance           = \"NONE\" -> (known after apply)\n      + snapshot_policies        = (known after apply)\n      + tags                     = (known after apply)\n      ~ type                     = \"Standalone\" -> (known after apply)\n      ~ unprotected              = true -> (known after apply)\n      ~ unreducible_data_gb      = 0 -> (known after apply)\n      + uuid                     = (known after apply)\n      ~ volume_ids               = [] -> (known after apply)\n      + vp_saved_percent         = (known after apply)\n      + workload                 = (known after apply)\n        # (2 unchanged attributes hidden)\n    }\n\nPlan: 0 to add, 1 to change, 0 to destroy.\n\n─────────────────────────────────────────────────────────────────────────────\n\nSaved the plan to: /tmp/tmp6f2o83k5.tfplan\n\nTo perform exactly these actions, run the following command to apply:\n    terraform apply \"/tmp/tmp6f2o83k5.tfplan\"\n",
            "stdout_lines": [
                "powermax_storagegroup.tf_sg: Refreshing state... [id=tf-sg2]",
                "",
                "Terraform used the selected providers to generate the following execution",
                "plan. Resource actions are indicated with the following symbols:",
                "  ~ update in-place",
                "",
                "Terraform will perform the following actions:",
                "",
                "  # powermax_storagegroup.tf_sg will be updated in-place",
                "  ~ resource \"powermax_storagegroup\" \"tf_sg\" {",
                "      ~ cap_gb                   = 0 -> (known after apply)",
                "      + child_storage_group      = (known after apply)",
                "      ~ compression              = true -> (known after apply)",
                "      + compression_ratio        = (known after apply)",
                "      ~ compression_ratio_to_one = 0 -> (known after apply)",
                "      + device_emulation         = (known after apply)",
                "      ~ id                       = \"tf-sg2\" -> (known after apply)",
                "      + maskingview              = (known after apply)",
                "      ~ name                     = \"tf-sg2\" -> \"tf-sg3\"",
                "      ~ num_of_child_sgs         = 0 -> (known after apply)",
                "      ~ num_of_masking_views     = 0 -> (known after apply)",
                "      ~ num_of_parent_sgs        = 0 -> (known after apply)",
                "      + num_of_snapshot_policies = (known after apply)",
                "      ~ num_of_snapshots         = 0 -> (known after apply)",
                "      ~ num_of_vols              = 0 -> (known after apply)",
                "      + parent_storage_group     = (known after apply)",
                "      + service_level            = (known after apply)",
                "      ~ slo                      = \"NONE\" -> (known after apply)",
                "      ~ slo_compliance           = \"NONE\" -> (known after apply)",
                "      + snapshot_policies        = (known after apply)",
                "      + tags                     = (known after apply)",
                "      ~ type                     = \"Standalone\" -> (known after apply)",
                "      ~ unprotected              = true -> (known after apply)",
                "      ~ unreducible_data_gb      = 0 -> (known after apply)",
                "      + uuid                     = (known after apply)",
                "      ~ volume_ids               = [] -> (known after apply)",
                "      + vp_saved_percent         = (known after apply)",
                "      + workload                 = (known after apply)",
                "        # (2 unchanged attributes hidden)",
                "    }",
                "",
                "Plan: 0 to add, 1 to change, 0 to destroy.",
                "",
                "─────────────────────────────────────────────────────────────────────────────",
                "",
                "Saved the plan to: /tmp/tmp6f2o83k5.tfplan",
                "",
                "To perform exactly these actions, run the following command to apply:",
                "    terraform apply \"/tmp/tmp6f2o83k5.tfplan\""
            ],
            "workspace": "default"
        }
    }
    
    PLAY RECAP ***************************************************************************************
    localhost   : ok=2    changed=0    unreachable=0    failed=0    skipped=0    ignored=0

    No changes are made and the Ansible module has captured the details of the changes that will be made if the plan is applied.

    Terraform destroy

    Finally we need to learn how to use “terraform destroy”. You might have guessed it by now. The native way of destroying something in Ansible is by setting the state to “absent”.

    ---
    - hosts: localhost
      gather_facts: no
    
      vars:
        project_dir: "/root/powermax" # dir that contains main.tf, ...
    
      tasks:
        - name: Run terraform
          community.general.terraform:
            project_path: '{{ project_dir }}'
            state: absent
            variables:
              sg_name: "{{ sg_name }}"
              password: "{{ password }}"
          register: output
    
        - debug:
            var: output

    Let’s run it and see what it does.

    root:~# ansible-playbook runtf.yml --extra-vars "sg_name=tf-sg2 password=TFp2ssw0rd"
    
    PLAY [localhost] ***************************************************************************************
    
    TASK [Run terraform] ***************************************************************************************
    changed: [localhost]
    
    TASK [debug] ***************************************************************************************
    ok: [localhost] => {
        "output": {
            "changed": true,
            "command": "/usr/bin/terraform destroy -no-color -auto-approve -lock=true -var sg_name=tf-sg2 -var password=smc",
            "failed": false,
            "outputs": {},
            "state": "absent",
            "stderr": "",
            "stderr_lines": [],
            "stdout": "powermax_storagegroup.tf_sg: Refreshing state... [id=tf-sg2]\n\nTerraform used the selected providers to generate the following execution\nplan. Resource actions are indicated with the following symbols:\n  - destroy\n\nTerraform will perform the following actions:\n\n  # powermax_storagegroup.tf_sg will be destroyed\n  - resource \"powermax_storagegroup\" \"tf_sg\" {\n      - cap_gb                   = 0 -> null\n      - compression              = true -> null\n      - compression_ratio_to_one = 0 -> null\n      - host_io_limit            = {} -> null\n      - id                       = \"tf-sg2\" -> null\n      - name                     = \"tf-sg2\" -> null\n      - num_of_child_sgs         = 0 -> null\n      - num_of_masking_views     = 0 -> null\n      - num_of_parent_sgs        = 0 -> null\n      - num_of_snapshots         = 0 -> null\n      - num_of_vols              = 0 -> null\n      - slo                      = \"NONE\" -> null\n      - slo_compliance           = \"NONE\" -> null\n      - srp_id                   = \"SRP_1\" -> null\n      - type                     = \"Standalone\" -> null\n      - unprotected              = true -> null\n      - unreducible_data_gb      = 0 -> null\n      - volume_ids               = [] -> null\n    }\n\nPlan: 0 to add, 0 to change, 1 to destroy.\npowermax_storagegroup.tf_sg: Destroying... [id=tf-sg2]\npowermax_storagegroup.tf_sg: Destruction complete after 0s\n\nDestroy complete! Resources: 1 destroyed.\n",
            "stdout_lines": [
                "powermax_storagegroup.tf_sg: Refreshing state... [id=tf-sg2]",
                "",
                "Terraform used the selected providers to generate the following execution",
                "plan. Resource actions are indicated with the following symbols:",
                "  - destroy",
                "",
                "Terraform will perform the following actions:",
                "",
                "  # powermax_storagegroup.tf_sg will be destroyed",
                "  - resource \"powermax_storagegroup\" \"tf_sg\" {",
                "      - cap_gb                   = 0 -> null",
                "      - compression              = true -> null",
                "      - compression_ratio_to_one = 0 -> null",
                "      - host_io_limit            = {} -> null",
                "      - id                       = \"tf-sg2\" -> null",
                "      - name                     = \"tf-sg2\" -> null",
                "      - num_of_child_sgs         = 0 -> null",
                "      - num_of_masking_views     = 0 -> null",
                "      - num_of_parent_sgs        = 0 -> null",
                "      - num_of_snapshots         = 0 -> null",
                "      - num_of_vols              = 0 -> null",
                "      - slo                      = \"NONE\" -> null",
                "      - slo_compliance           = \"NONE\" -> null",
                "      - srp_id                   = \"SRP_1\" -> null",
                "      - type                     = \"Standalone\" -> null",
                "      - unprotected              = true -> null",
                "      - unreducible_data_gb      = 0 -> null",
                "      - volume_ids               = [] -> null",
                "    }",
                "",
                "Plan: 0 to add, 0 to change, 1 to destroy.",
                "powermax_storagegroup.tf_sg: Destroying... [id=tf-sg2]",
                "powermax_storagegroup.tf_sg: Destruction complete after 0s",
                "",
                "Destroy complete! Resources: 1 destroyed."
            ],
            "workspace": "default"
        }
    }
    
    PLAY RECAP ***************************************************************************************
    localhost  : ok=2    changed=1    unreachable=0    failed=0    skipped=0     ignored=0

    The storage group resource has been destroyed and that shows in Ansible as a task with a status of “changed”. The “stdout” and “stdout_lines” parameters provide a record of what was destroyed.

    In summary, in this article we have seen how to use the terraform Ansible module to plan, apply and destroy Terraform projects. In doing that, organizations can leverage a tool like AWX or RedHat AAP to provide RBAC, strong credential management and a powerful upstream REST API and integrate with other tools like ITSM etc. AWX and AAP can also became a polyglot automation platform capable of running the two most popular automation tools out there to satisfy both traditional infrastructure teams and developers.

  • Exploring the Strengths and Trade-offs of Fine-tuning and RAG in Language Models

    In the ever-evolving landscape of artificial intelligence, the incorporation of domain-specific knowledge into language models (LLMs) is not just a lofty goal—it’s a mission-critical aspect of model performance. This is where fine-tuning and Retriever-Reader (RAG) come into the picture, two powerful approaches with distinct methodologies for imbuing models with domain-specific prowess. As the Director of AI Research at a tech startup, investing in the right approach to empower language models with knowledge is a debate that rages on in our weekly strategy meetings. In this piece, I dissect the benefits and trade-offs of both methods, aiming to help data scientists, AI enthusiasts, and tech professionals make informed decisions regarding the enhancement of LLMs.

    Introduction

    The modern data scientist wields the power to curate a model’s understanding to an unprecedented degree. Incorporating domain knowledge has become less of an afterthought and more of the central piece to the puzzle of AI applications. As established models like GPT-3 demonstrate extraordinary capabilities, the question of specialized knowledge arises. Both fine-tuning and RAG have stepped forward as capable candidates for augmenting language models, offering different paths to the same destination.

    Fine-tuning: Leveraging Existing Models

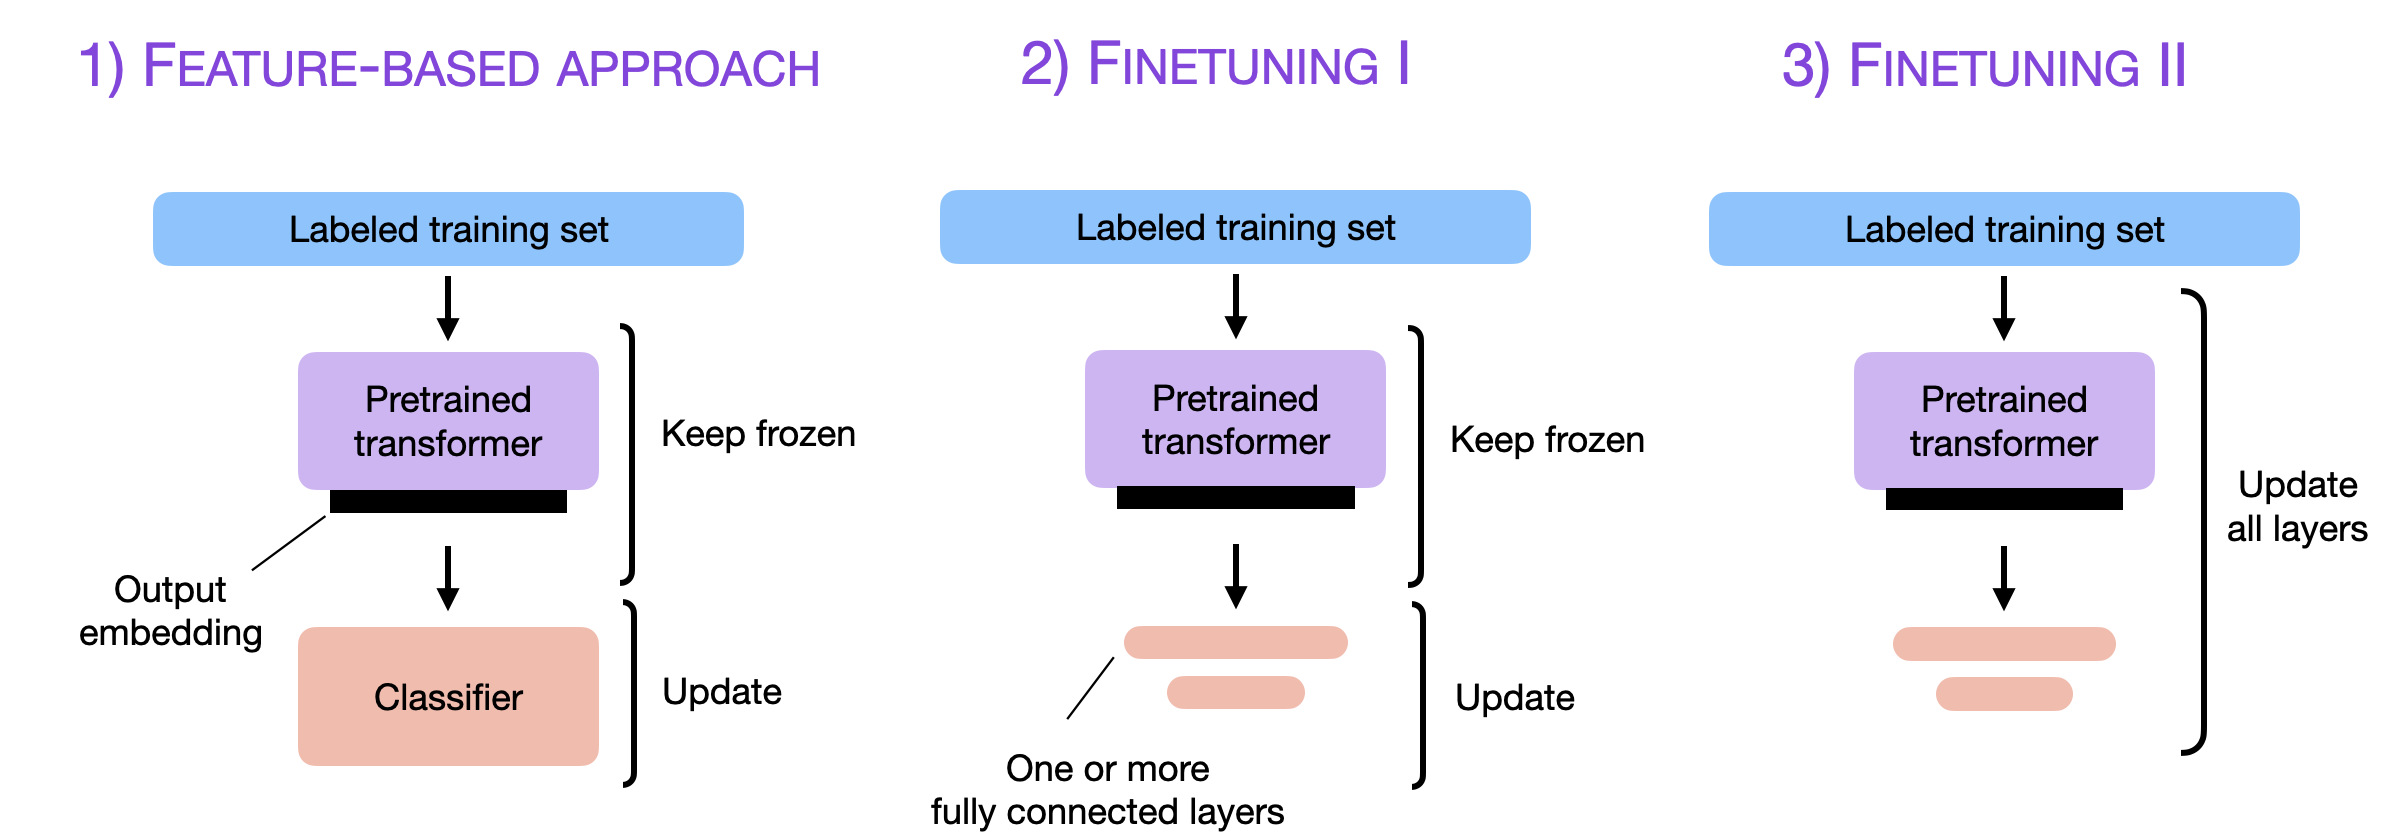
    Fine-tuning involves starting with a pre-trained model and updating its weights using labeled examples from within the target domain. The rationale is simple: rather than reinventing the wheel, one can build upon the wealth of knowledge already stored within established models.

    https://sebastianraschka.com/images/blog/2023/llm-finetuning-llama-adapter/classic-flowchart.png

    The Fine-tuning Approach in Depth

    Fine-tuning has gained popularity due to its relatively lower resource consumption compared to training from scratch. Pre-trained models come with an inherent understanding of language and are adept at various natural language processing (NLP) tasks. By fine-tuning these models, often with a smaller, domain-specific dataset, we can specialize the general model to fit particular needs.

    Benefits of Fine-tuning

    • Faster Deployment: Leveraging an existing model allows for a quicker setup, reducing the time from development to deployment significantly.
    • Capitalizing on Pre-trained Weights: The pre-training phase is costly in terms of computation and time. Fine-tuning capitalizes on this investment, using pre-trained weights as a head start for domain tasks.
    • Leveraging Pre-Trained Models: Pre-trained models are increasingly sophisticated and capture various nuances of human language.

    Examples of Successful Applications

    The medical field, for instance, has seen strides with fine-tuned models specializing in entity recognition, question answering, and summarization tasks. In patient data analysis, these models can parse through vast amounts of unstructured text, extracting relevant information with precision.

    RAG: Incorporating Explicit Knowledge

    RAG, on the other hand, is a more recently introduced framework designed to incorporate external knowledge sources into the inference process. It aims to enhance the rationality and awareness of AI systems by allowing them to query reference materials as part of their preliminary thinking.

    The RAG Framework in Depth

    The RAG framework consists of two components: a retriever and a reader. The retriever uses a query to extract relevant passages from a knowledge source, and the reader processes these passages to find an answer or provide context.

    Image courtesy – https://lilianweng.github.io/posts/2020-10-29-odqa/

    Advantages of RAG

    • Handling Out-of-Domain Queries: RAG is capable of tackling a broader set of tasks, not just those within the dataset scope, by referring to the internet or other massive knowledge bases.
    • Interpretability: The retriever component offers insights into the knowledge basis of the model’s decisions, essential for accountability and trust in AI systems.

    Real-World Use Cases

    In legal research, for example, RAG models can sift through laws, cases, and precedents to provide up-to-date advice, cross-referencing information as legal landscapes shift. As such, the legal domain provides a fertile ground for RAG models to shine, reshaping how we approach legal queries and research.

    Strengths and Weaknesses of Fine-tuning

    Fine-tuning isn’t without its downsides. While it excels in many facets, particularly speed and leveraging existing models, it does come with concerns over model performance in unique domains.

    Discussion of the Strengths

    Fine-tuned models often achieve better performance on in-domain tasks, as they’ve been trained to recognize and respond to specific patterns and language nuances within the domain.

    Analysis of the Weaknesses

    Fine-tuned models can be sensitive to the distribution and quality of the training data. Overfitting, a common problem, may occur, leading to less generalizable models. Moreover, fine-tuning can inadvertently strip away some of the broader knowledge captured in the pre-training phase.

    Strengths and Weaknesses of RAG

    RAG’s ability to query large knowledge bases is a distinct advantage but not without its own set of challenges.

    Examination of the Strengths

    RAG models offer improved interpretability, particularly through the retriever’s explicit referencing of the source of its decisions. They also enjoy the benefit of not being overly specialized to a specific domain, serving as a more flexible solution.

    Analysis of the Weaknesses

    However, RAG’s computational requirements are significant. Each query necessitates running through a retrieval system, which can be a bottleneck in terms of the model’s scalability. There’s also the potential for errors in retrieving and parsing large external datasets.

    Trade-offs and Considerations

    When facing a decision between fine-tuning and RAG, it’s critical to assess the nuances of each approach and how they align with the project’s objectives and constraints.

    Comparison of the Two Approaches

    • Performance: Fine-tuned models often outperform RAG models on in-domain tasks. However, RAG’s ability to call upon external knowledge can provide a richer context and improve overall understanding.
    • Flexibility: RAG models are inherently more flexible, handling out-of-domain queries with ease. Fine-tuned models may struggle with tasks beyond their initial scope.
    • Resource Requirements: Fine-tuning generally requires fewer resources, both in terms of infrastructure and data. RAG, with its need for knowledge bases and retrieval systems, tends to be more resource-intensive.

    Factors to Consider

    Certain factors, such as the availability of domain-specific data, the tolerance for uncertainty in results, and the willingness to invest in computational power, should heavily influence the choice between these two approaches.

    Conclusion

    In navigating the complex terrain of domain knowledge incorporation in language models, our journey is one of constant assessment and adaptation. Both fine-tuning and RAG represent leading strategies, each replete with strengths and trade-offs. While there may be no one-size-fits-all answer, the key to unlocking the potential of AI systems lies in understanding and consciously selecting the tool that best suits the task at hand.

    As we stride forward, it’s clear that a balanced approach, perhaps even a hybrid of fine-tuning and RAG, could be the most promising direction. It’s incumbent upon us as practitioners to continue probing, experimenting, and pushing the boundaries of what is possible with language models. By doing so, we will not only elevate the efficiency of our AI systems but also deepen our understanding of what it truly means to teach machines with human wisdom.

    Investing in the right approach isn’t just about model performance; it’s about the ethical and practical implications of the choices we make in the burgeoning field of AI. The confluence of domain knowledge and language models is a domain ripe with potential, and as we integrate these methods into our systems, it will be exciting to see how they unfold, bringing us discoveries, better performance, and perhaps most importantly, a greater appreciation for the delicate art of AI model construction.